A practical guide for a company connecting online-store orders with ERP inventory and handling orders, cancellations and returns in a testable way.
Why stock synchronisation is a business process, not merely an API connection
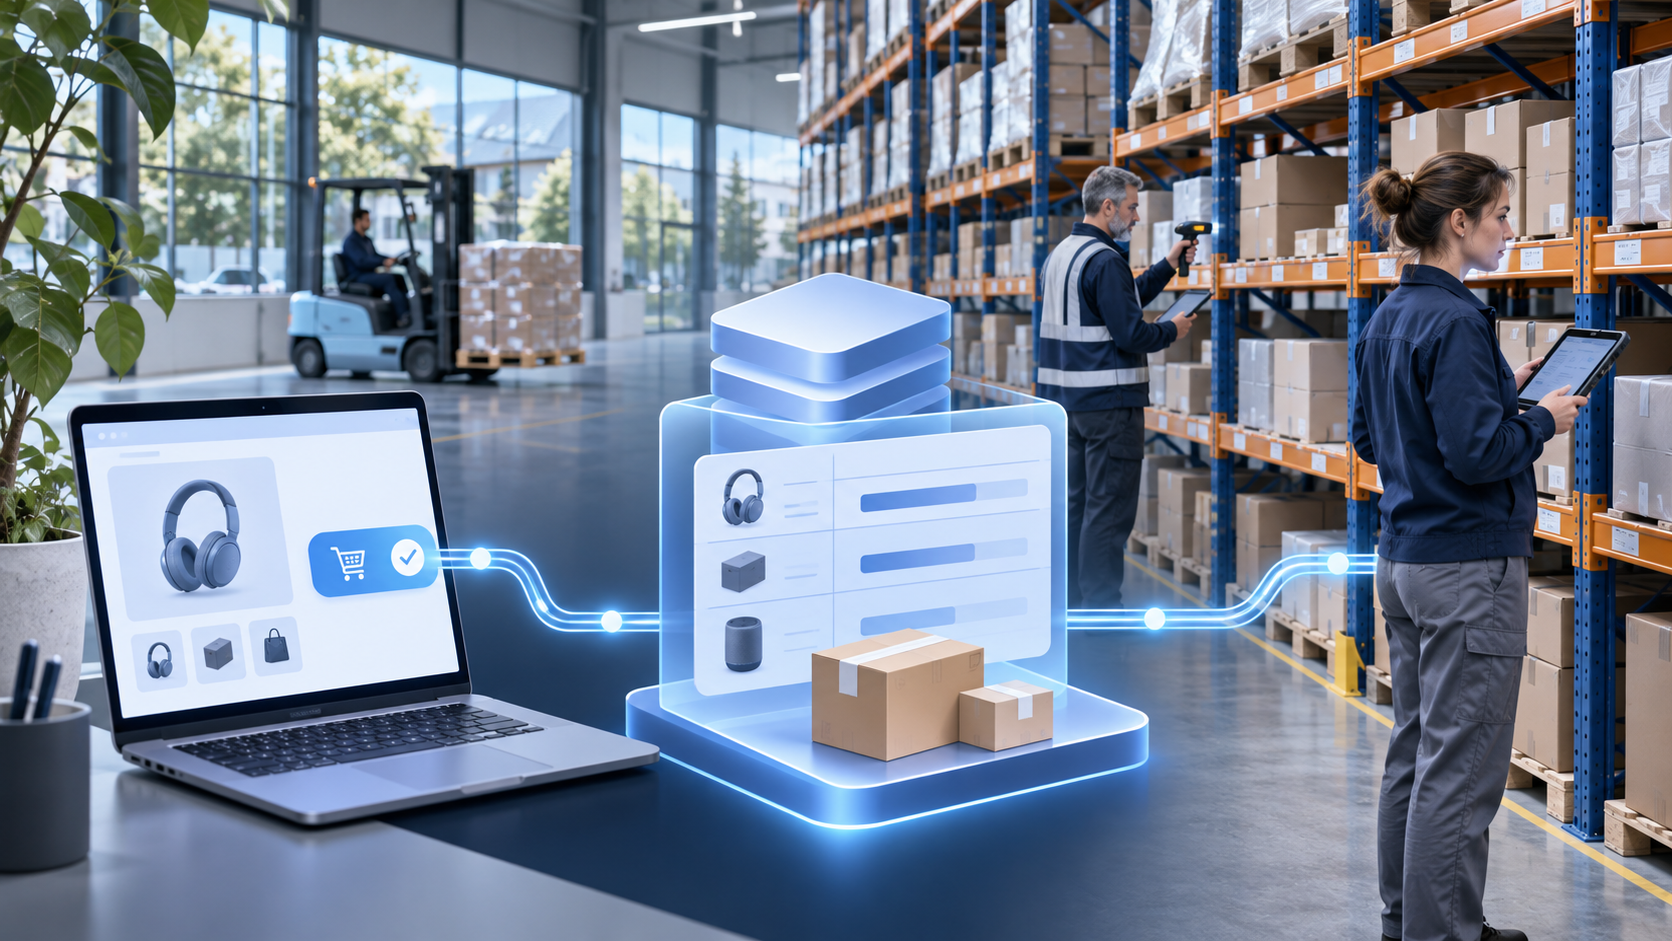
An online store makes a sales promise when a shopper sees an item as available, while the ERP often records the warehouse position. The integration must keep those views consistent while orders, cancellations, picking and returns change the stock. A successful request is useful only when it produces the intended business state.
Define “physical stock”, “available to sell”, “reserved”, “in transit” and “blocked”. Every value needs a unit, warehouse, product variant, event time and source system. Without this vocabulary, the same number in two systems can describe different quantities and a technical match can hide an operational disagreement.
A common failure appears when the store shows ten units, the ERP knows about eight, and two of those are reserved for another channel. The customer receives a confirmation the warehouse cannot fulfil. The damage extends beyond data: it affects payment, delivery promises, customer support and the credibility of the shop.
Control begins with a process map and an owner for every state. The team decides when stock is reserved, when a reservation becomes an issue from stock, and how either action is reversed. These rules are approved before code, so tests prove a business outcome instead of checking only an HTTP status.
Illustrative example: the store displays five units, one is held by an unpaid reservation and one is undergoing a return inspection. If three units are available to sell, that is the quantity the sales channel should receive. This example explains the method; it is not a CANIMAPS DIGITAL client result or price.
Assign one system of responsibility for every stock decision
An integration needs a clear answer about which system can make the final stock decision. The ERP may own warehouse accounting while the store manages short reservations. In another organisation a warehouse management system fills that role. The important point is unambiguous responsibility rather than a particular product name.
Describe the writing direction for every field. For example, the ERP publishes physical stock, the store sends a reservation request, and an integration service calculates availability. If two systems can overwrite the same field freely, the last request becomes the truth by accident and an earlier valid decision can disappear.
A typical failure is a loop: the ERP sends 12, the store responds with 11, the ERP interprets that response as a correction and publishes 12 again. Logs show heavy activity even though the business process is stuck. The loop consumes API capacity and can obscure real order events.
Use an origin marker, event identifier and version. A receiver must not treat its own earlier message as a new business event. Route disputed adjustments to a review queue instead of selecting a random winner. The responsibility table should also name the person authorised to approve a warehouse correction.
Illustrative example: a warehouse operator records one damaged unit in the ERP. The ERP publishes version 41 with stock 24 and reason “damage”. The store reduces availability but does not return the same value as a manual correction. The test checks the number, origin, version and reason.
Map products, variants, warehouses and units
Stock synchronisation starts with identity. One item can have an ERP code, store SKU, barcode and supplier number. A size or colour variant is a distinct stock object. Matching only on a product name eventually links similar items incorrectly and makes a discrepancy difficult to investigate.
For every field, record its source, format, requirement, example and transformation. Include warehouse, batch or serial number, unit and time zone where relevant. If the ERP counts cases while the shop sells pieces, the conversion factor must be controlled, versioned and visible to operators.
A failure occurs when a new variant exists on one side only. The integration receives an unknown SKU and either ignores it or guesses the nearest record. Silent rejection creates unexplained drift, while automatic guessing can change stock for the wrong item.
Put unknown identifiers in a quarantine queue. The event is retained but cannot change stock until an authorised person approves the mapping. A practical way to structure this work is described in the article about building a data field map before system integration.
Illustrative example: ERP code A-104 and store SKU BLUE-M refer to the same medium blue shirt. The map keeps both values and a stable internal identifier. When another warehouse is added, it becomes a new inventory dimension rather than a second product.
Create an order and reserve stock safely
A new order does not have to mean the same reservation point in every company. Some reserve on submission, others after payment or fraud review. The rule should be deliberate because it balances the risk of overselling against the risk of blocking stock for orders that will never be completed.
An order event needs an immutable order ID, line ID, product variant, quantity, warehouse and state. Give the reservation its own ID and expiry time. It can then be cancelled or extended directly without reconstructing the business object from free text or from an entire order snapshot.
A failure can occur when the shopper presses a button twice or a payment provider repeats a notification. Two technical requests must not create two business reservations. Another risk is an ambiguous timeout: the store receives an error although the ERP already saved the reservation and then tries again.
Combine an idempotency key, a unique event ID and a status read after an ambiguous response. A repeated request returns the outcome of the existing reservation. Logs connect the attempt to the order while excluding personal information that is not required for diagnosis.
Illustrative example: order O-7001 reserves two units. The connection drops after the ERP commits the change. The store repeats the message with the same event ID; the receiver finds reservation R-910 and returns its state. Availability decreases once, and the operator can trace both delivery attempts.
Cancel a reservation without adding stock twice

Cancellation is not simply a negative order. The item may be reserved, picked, handed to a carrier or already issued from stock. Each state requires a different reversal. A universal “add one” rule can increase availability for an item that is no longer physically present.
Carry the original reservation or line ID, cancelled quantity, reason, time and initiator. For a partial cancellation, preserve the quantity that still needs fulfilment. A state machine prevents a transition from “shipped” directly to “reservation released” and forces the appropriate return or delivery process.
A failure occurs when the store and a support agent cancel the same line at almost the same time. Both channels read the old state and request a release. If the receiver merely adds a quantity, inventory becomes one unit too high.
Enforce uniqueness for the cancellation operation and lock or compare the reservation version. In one transaction, the receiver checks the current state, releases only the quantity still reserved and records the result. On a conflict it returns the current state rather than silently making another adjustment.
Illustrative example: a shopper cancels one of three ordered units. The active reservation falls from three to two, and availability rises by one. A repeated notification returns the same recorded result but does not change stock again.
Treat a return as receiving, inspection and a disposition decision

A customer return does not immediately become saleable stock. The warehouse must receive it, match it to an authorisation and often inspect its condition. Some units return to a shelf, while others move to repair, quarantine or write-off.
Separate “return requested”, “received”, “inspected” and “disposition approved”. Keep the return ID, original order line, received quantity, warehouse and final disposition. Change saleable stock only through the step approved by the operating process.
A common failure is to confuse a refund with physical receipt. Finance can complete a refund while the parcel remains in transit. If the integration increases availability on the refund event, the store may sell an item the warehouse has not received.
Use distinct finance and logistics events. At the return workstation, the operator selects a reason and inspection result from controlled values. The integration publishes an inventory change after the correct warehouse state. The audit trail records who made the decision and when.
Illustrative example: a shopper returns two units and one is damaged. Both enter quarantine on receipt. After inspection, one becomes saleable and one is written off. The store increases availability by one even though the refund covers both units.
Control delayed events and out-of-order delivery
Network messages do not always arrive in business order. A cancellation can reach the ERP before its reservation, or yesterday’s snapshot can arrive after today’s adjustment. Receipt time alone is therefore not reliable evidence of business sequence.
Give every event a business time, creation time, source version and identifier. The receiver stores the last accepted version for the relevant object. When the source cannot provide a monotonic version, the integration needs an explicit comparison rule and a review path for ambiguous cases.
A stale “stock 20” message may overwrite a newer “stock 18”. Both systems look healthy while data moves backwards in time. A late reservation applied after its cancellation is even more dangerous because it leaves stock blocked without an active order.
Detect stale events, retain them for audit and prevent them from changing inventory. If a cancellation arrives first, hold it briefly or store a tombstone so the later reservation is immediately recognised as already cancelled.
Illustrative test: send reservation version 41 followed by cancellation version 42, but deliberately reverse their delivery order. The final state must contain no active reservation and availability must equal the starting value. The test also checks the audit entry and alert.
Handle duplicates, retries and idempotency
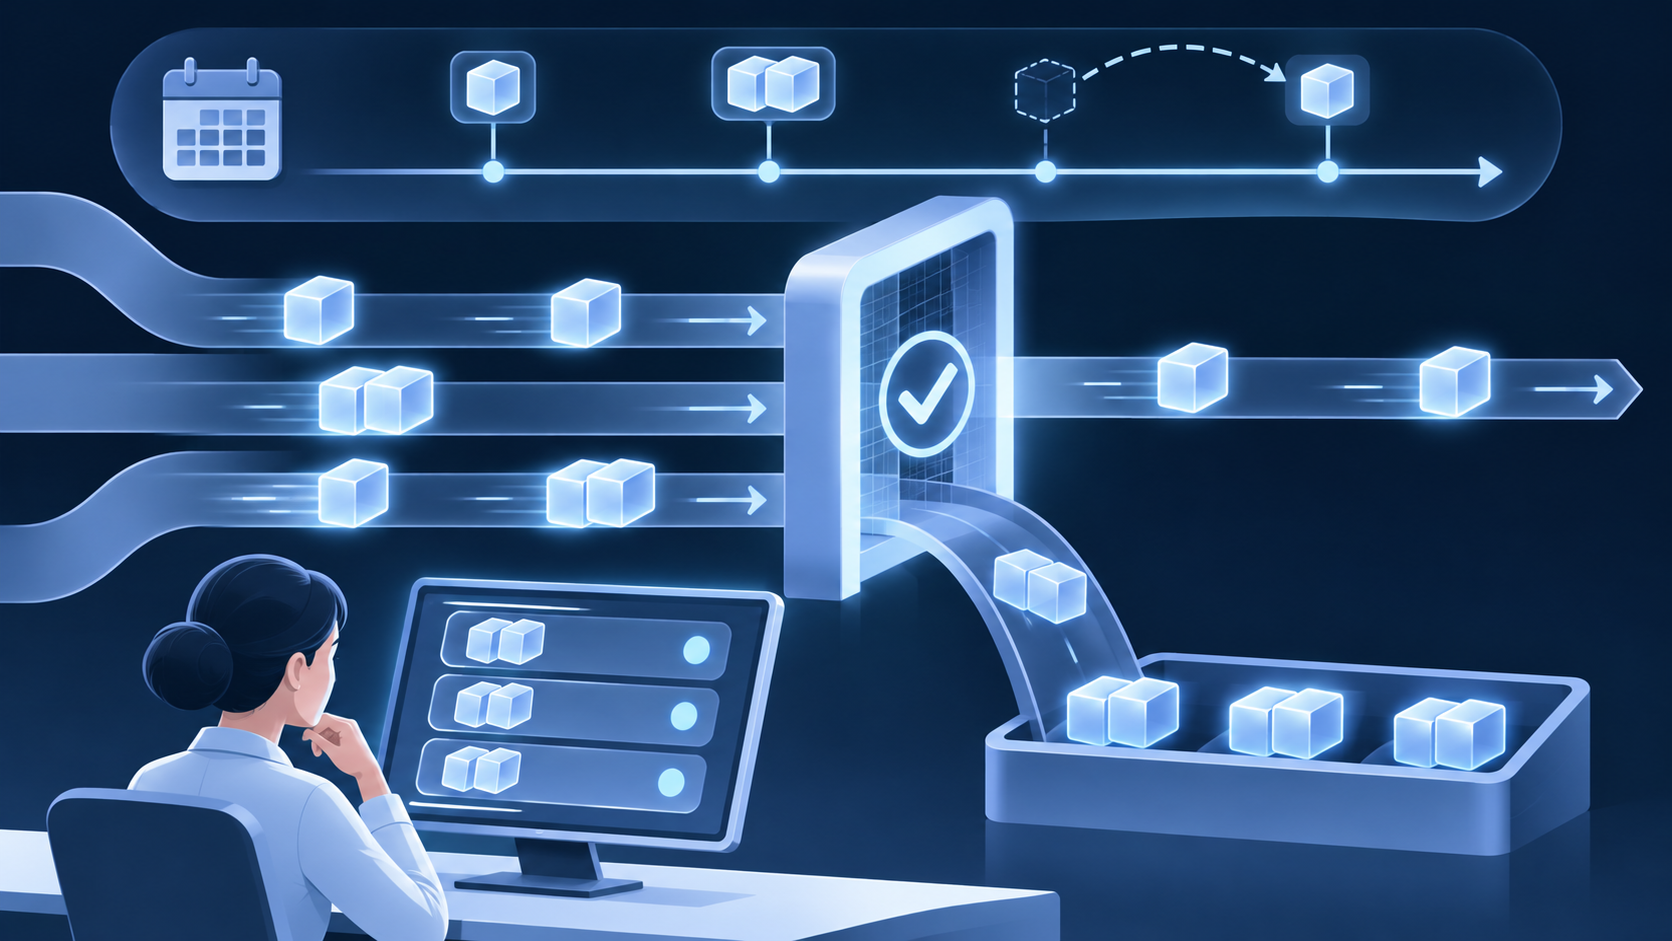
Retries are a normal part of reliable delivery. A sender may not know whether the receiver committed a change before the connection failed. Trying never to resend raises the risk of lost updates; the safer objective is to accept a retry without applying a second business effect.
Bind an idempotency key to a specific action such as reserving or cancelling an order line. Store the key, a request fingerprint and the result. If the same key arrives with different content, treat it as a conflict rather than a fresh adjustment.
A duplicate filter held only in memory forgets its history after a restart. A retention period that is too short also lets an old retry modify stock again. Choose the window from the real maximum delivery, retry and recovery period rather than from an arbitrary cache default.
Use a persistent event register, a unique database constraint and a deterministic response. Send the same event two, five and ten times, including parallel requests. Inventory must change once while a metric records how many duplicates were received.
Illustrative test: cancellation C-88 increases availability from 14 to 15. The same event returns ten minutes later and again after a server restart. Both retries return the stored result of 15; they never produce 16 or 17.
Use events for speed and snapshots for reconciliation
An event stream communicates changes quickly, while a periodic snapshot can reveal a missed or incorrectly processed event. The approaches serve different purposes and work well together. Events maintain day-to-day flow; reconciliation checks the aggregate state.
A snapshot needs an extraction time, warehouse, variant and comparable stock type. A reconciliation job must not blindly overwrite values while new orders continue. It should find differences, classify them and apply a correction with a version check.
A nightly import can overwrite orders processed this morning when its data is stale. The opposite extreme is relying only on events and never checking the whole state. One lost message can then remain unnoticed for months.
Create a reconciliation report with thresholds, reasons and owners. Known small differences may be classified automatically, while unexplained cases go to review. After correction, record the root cause so reconciliation does not become a permanent manual substitute for a reliable integration.
Illustrative example: a nightly comparison finds three mismatched SKUs. One is a pending return, one is an unknown variant in quarantine, and one is a delayed order event. The tool does not write one universal “correct number”; it gives the operator evidence for every difference.
Monitor business outcomes and assign incident responsibility
An integration can return HTTP 200 and still produce the wrong business result. Add process measures to technical metrics: the age of unprocessed events, number of stock differences, reservations without orders and returns that remain in quarantine too long.
Separate information, warning and incident levels. Every signal needs a threshold, responder, service window and escalation path. Logs should include a correlation ID, system, object, action and result while protecting customer data and access secrets.
Alert fatigue appears when thousands of low-value messages hide one important incident. An alert without an owner also becomes permanent background noise. The team must know who repairs transport, who approves inventory and who informs customer support.
Use an incident runbook: pause only the risky write flow, preserve events in a queue, identify the last safe version, fix the cause, replay safely and reconcile. Afterward, confirm whether the alert fired early enough and whether the evidence was sufficient.
Illustrative example: the duplicate rate rises sharply although stock still matches. The monitor creates a warning because the signal can reveal a sender retry loop. An operator follows the correlation ID and stops the repeater before it fills the queue or delays order processing.
Build a test matrix before release
One successful order proves too little. Include full and partial orders, payment failure, cancellation before and after picking, partial return, damaged goods, unknown SKU, delayed delivery and duplicate delivery in the test matrix.
For every scenario, record starting inventory, action order, expected ERP state, expected store state, log entry and alert. Test data should be recognisable and separated from production. Both the technical owner and the warehouse or order-process owner approve the outcome.
Comparing only the final number can hide two offsetting defects, such as a double reservation followed by a double cancellation. Inspect the event history, unique identifiers and permitted state transitions as well as the quantity.
Repeat the same dataset, apply a peak load and recover after a connection interruption. Two mandatory cases deserve special attention: a message arrives after a controlled delay, and an identical event arrives several times.
Illustrative test starts with 20 units. An order reserves three, one line is cancelled, two units ship, and later one is returned and becomes saleable after inspection. The matrix shows every intermediate state, not just the final quantity of 19.
Plan a controlled rollout and keep an operational checklist
Roll out in stages: first complete the data map and read-only comparison, then use one warehouse or product group, and only then enable limited writes. Keep a rollback route so automated writes can be paused without losing queued events.
Before launch, approve the system of record, state machine, identifier map, idempotency retention, reconciliation cadence, alert thresholds and responsibility matrix. Document API limits, credential rotation, the personal-data footprint and the fallback operating procedure.
A project can fail when it is considered finished as soon as the first message transfers successfully. Products, warehouses, promotions and ERP configuration continue to change. The integration needs an owner, a change procedure and a recurring recovery test.
Review incidents, duplicates, delays, unknown SKUs, reconciliation differences and upcoming system changes each month. For a broader view of boundaries and protected data, see the article about Private AI integration with ERP and accounting.
The practical decision is not “does the API work?” but “does every order, cancellation and return path create a provable stock outcome?” Start with one process map and ten scenarios, then expand coverage. Primary technical references: WooCommerce REST API documentation and WooCommerce webhook documentation.
Author: Rolands Zauls. Publisher: CANIMAPS DIGITAL.
Pre-production checklist. In one review, record the starting stock for every test SKU, the warehouse, the available-to-sell formula and the system authorised to approve an adjustment. Document when a reservation begins, when it expires, how a partial cancellation works and which return inspection decision can restore saleable stock. Every event has an immutable ID, origin, business time, version and correlation ID. Before enabling writes, run a delayed-event test, parallel duplicate test, connection failure after commit and replay after server restart. Confirm that one business event changes inventory once, a stale version is rejected and an unknown SKU enters quarantine. The reconciliation report must show the difference, likely reason, last accepted version and owner. Every alert has a threshold, recipient and action. On launch day, begin with a limited warehouse or product group, observe order, cancellation and return paths, then compare a full snapshot. If the outcome differs, pause only automated writing, preserve incoming events and return to the last verified version. Replay messages with the original identifiers so recovery does not create duplicates. Finally, the process owner signs off the physical and saleable result, while the technical owner retains the request order, responses, correlated logs and reconciliation evidence. This turns launch into a verifiable business change rather than a one-off technical demonstration.
Before final approval, the process owner compares order lines with inventory movements, the technical owner confirms that queued, duplicate and stale events are visible, and the warehouse representative verifies a physical sample. If those three sources disagree, the rollout remains limited and the difference is investigated through the correlation ID. Coverage expands only after the evidence matches, reducing the chance that a technically quiet defect becomes incorrect availability across the catalogue.